
Case 01Multimodal RAG · Video understanding
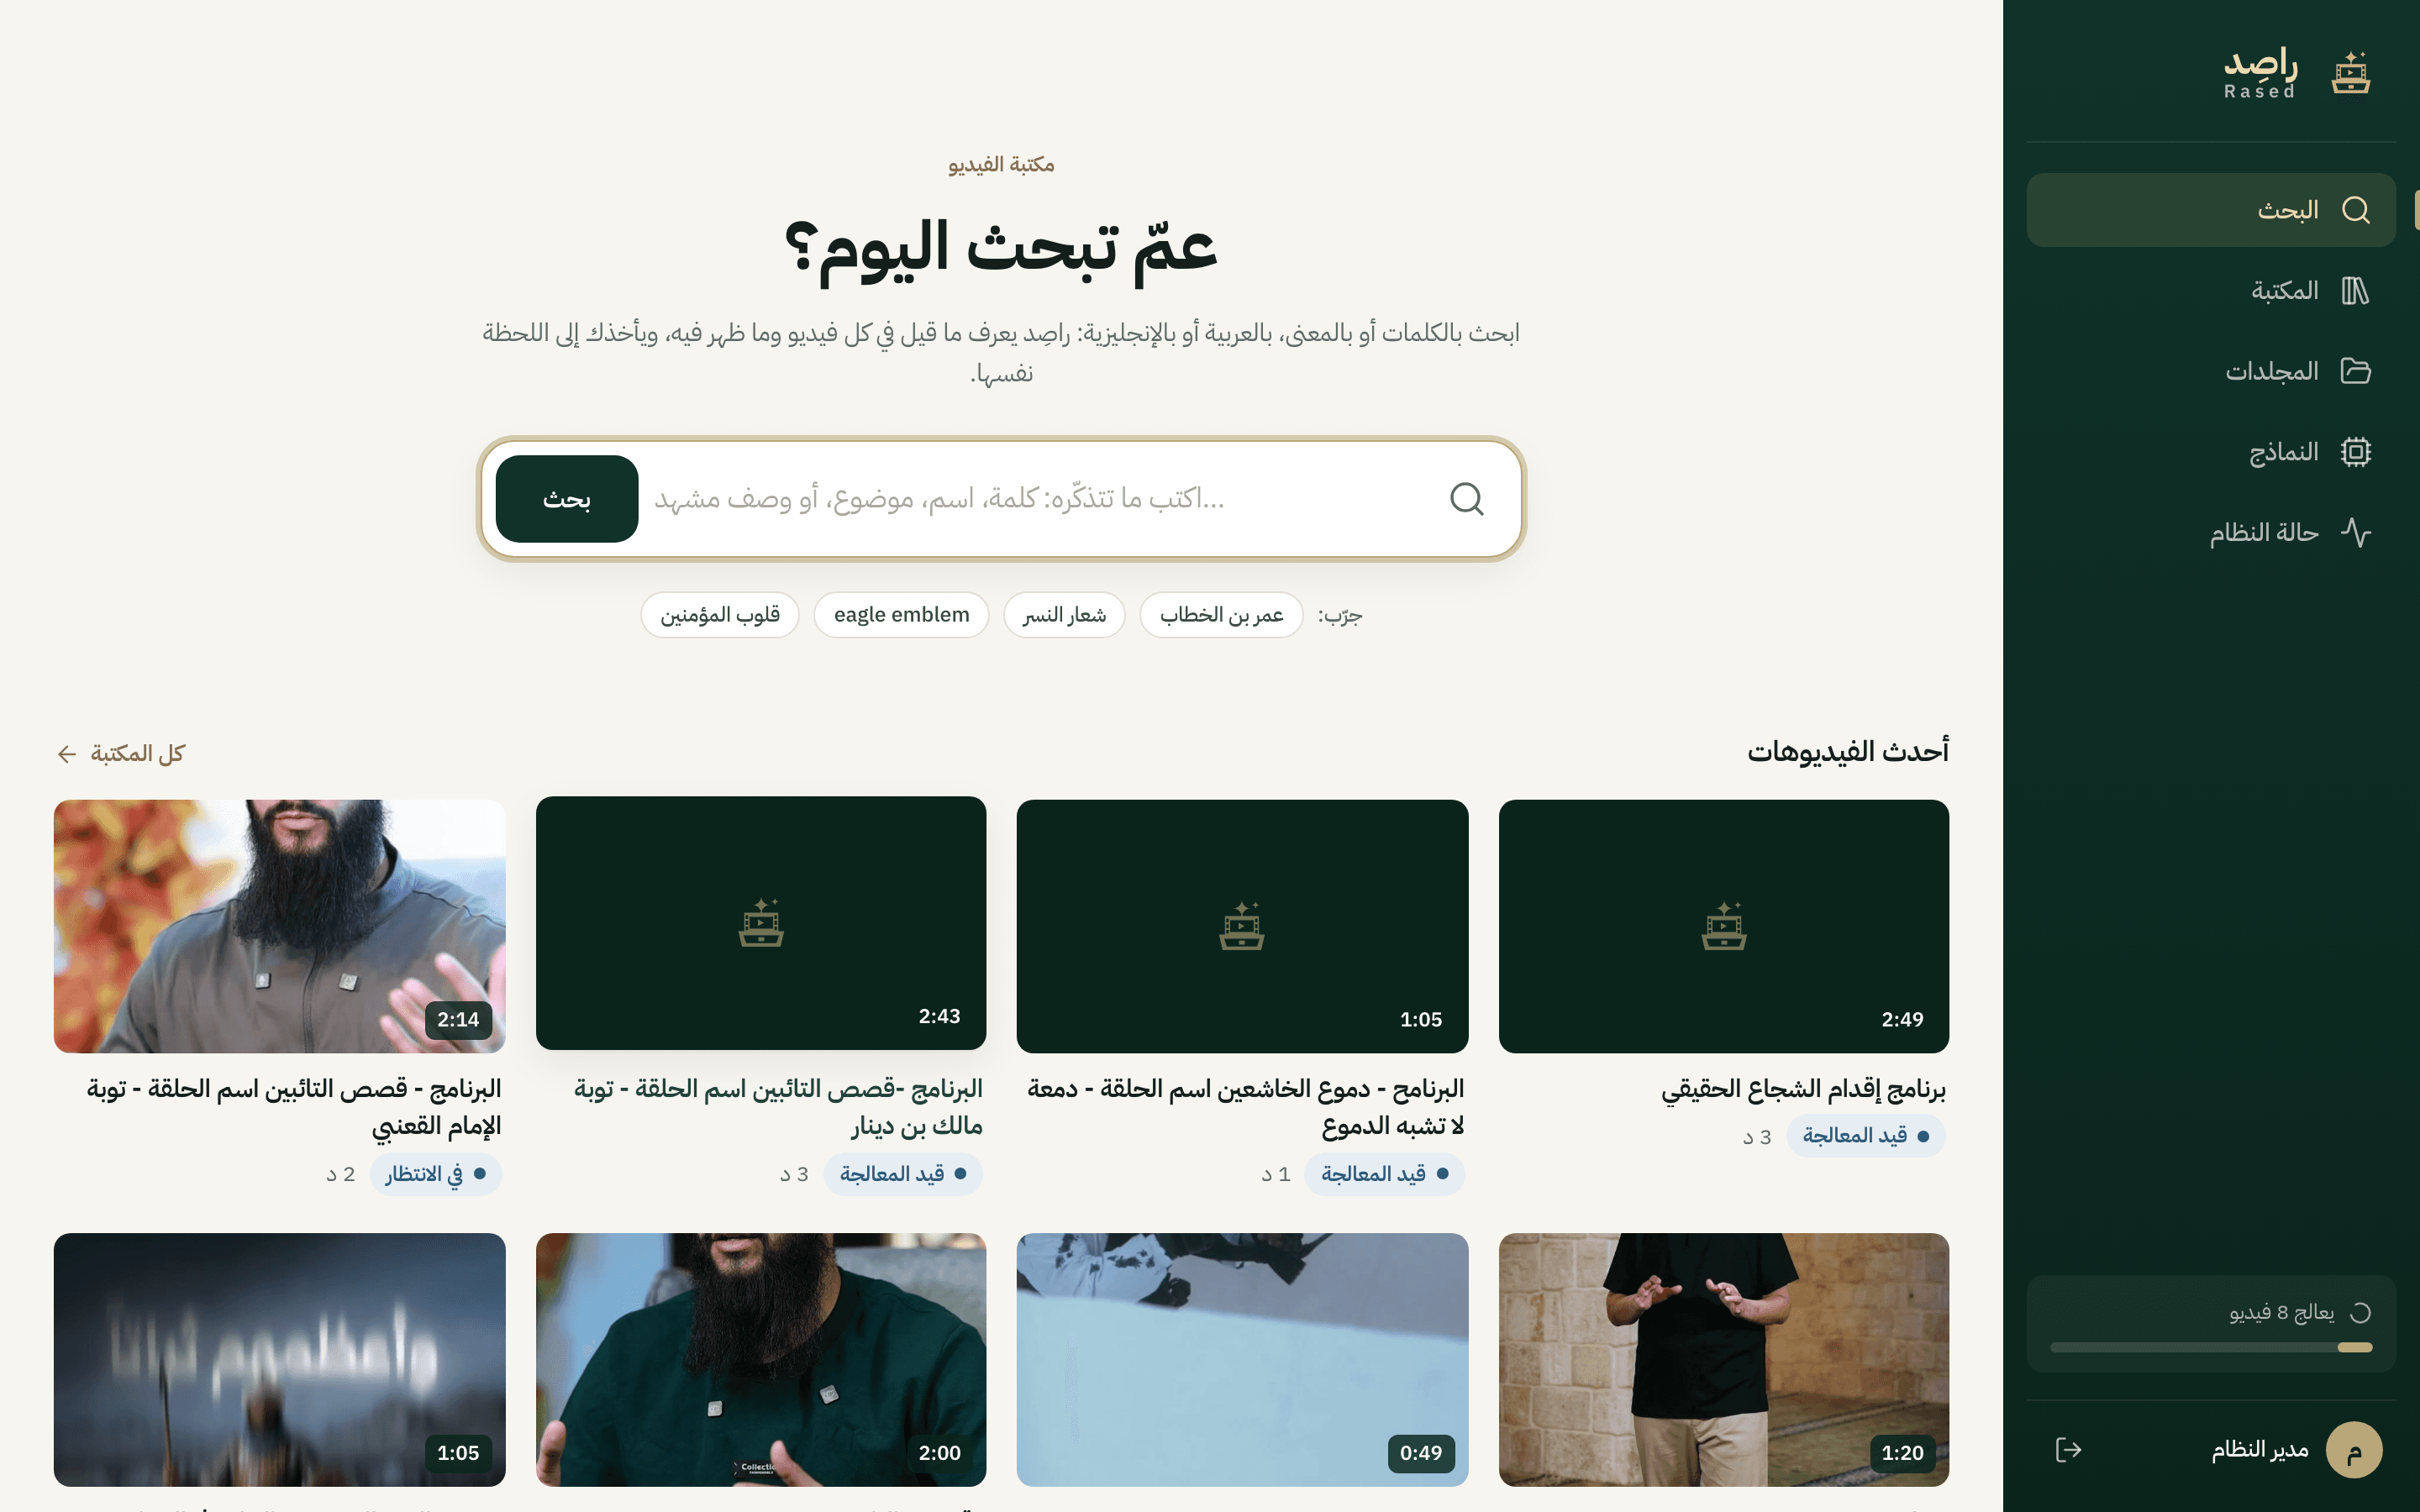
Every video described. Every moment searchable.راصِد
- Year
- 2026
- Status
- v0.1 · server & desktop
- Discipline
- Multimodal RAG · Video understanding
- 5
- local models
- 3
- retrievers fused
- 0
- bytes to the cloud
01 — The problem
Archives of Arabic video are effectively unsearchable: filenames say nothing, transcripts don’t exist, and sending footage to a cloud API is not an option for the organisations that own it. They needed recall at the level of a sentence or a scene, with nothing leaving the building.
A video library that watches and listens once — on your own hardware — then writes a title, summary, chapters, people and places for every file, and finds the exact second you remember, in Arabic or English.
02 — What I built
- 01
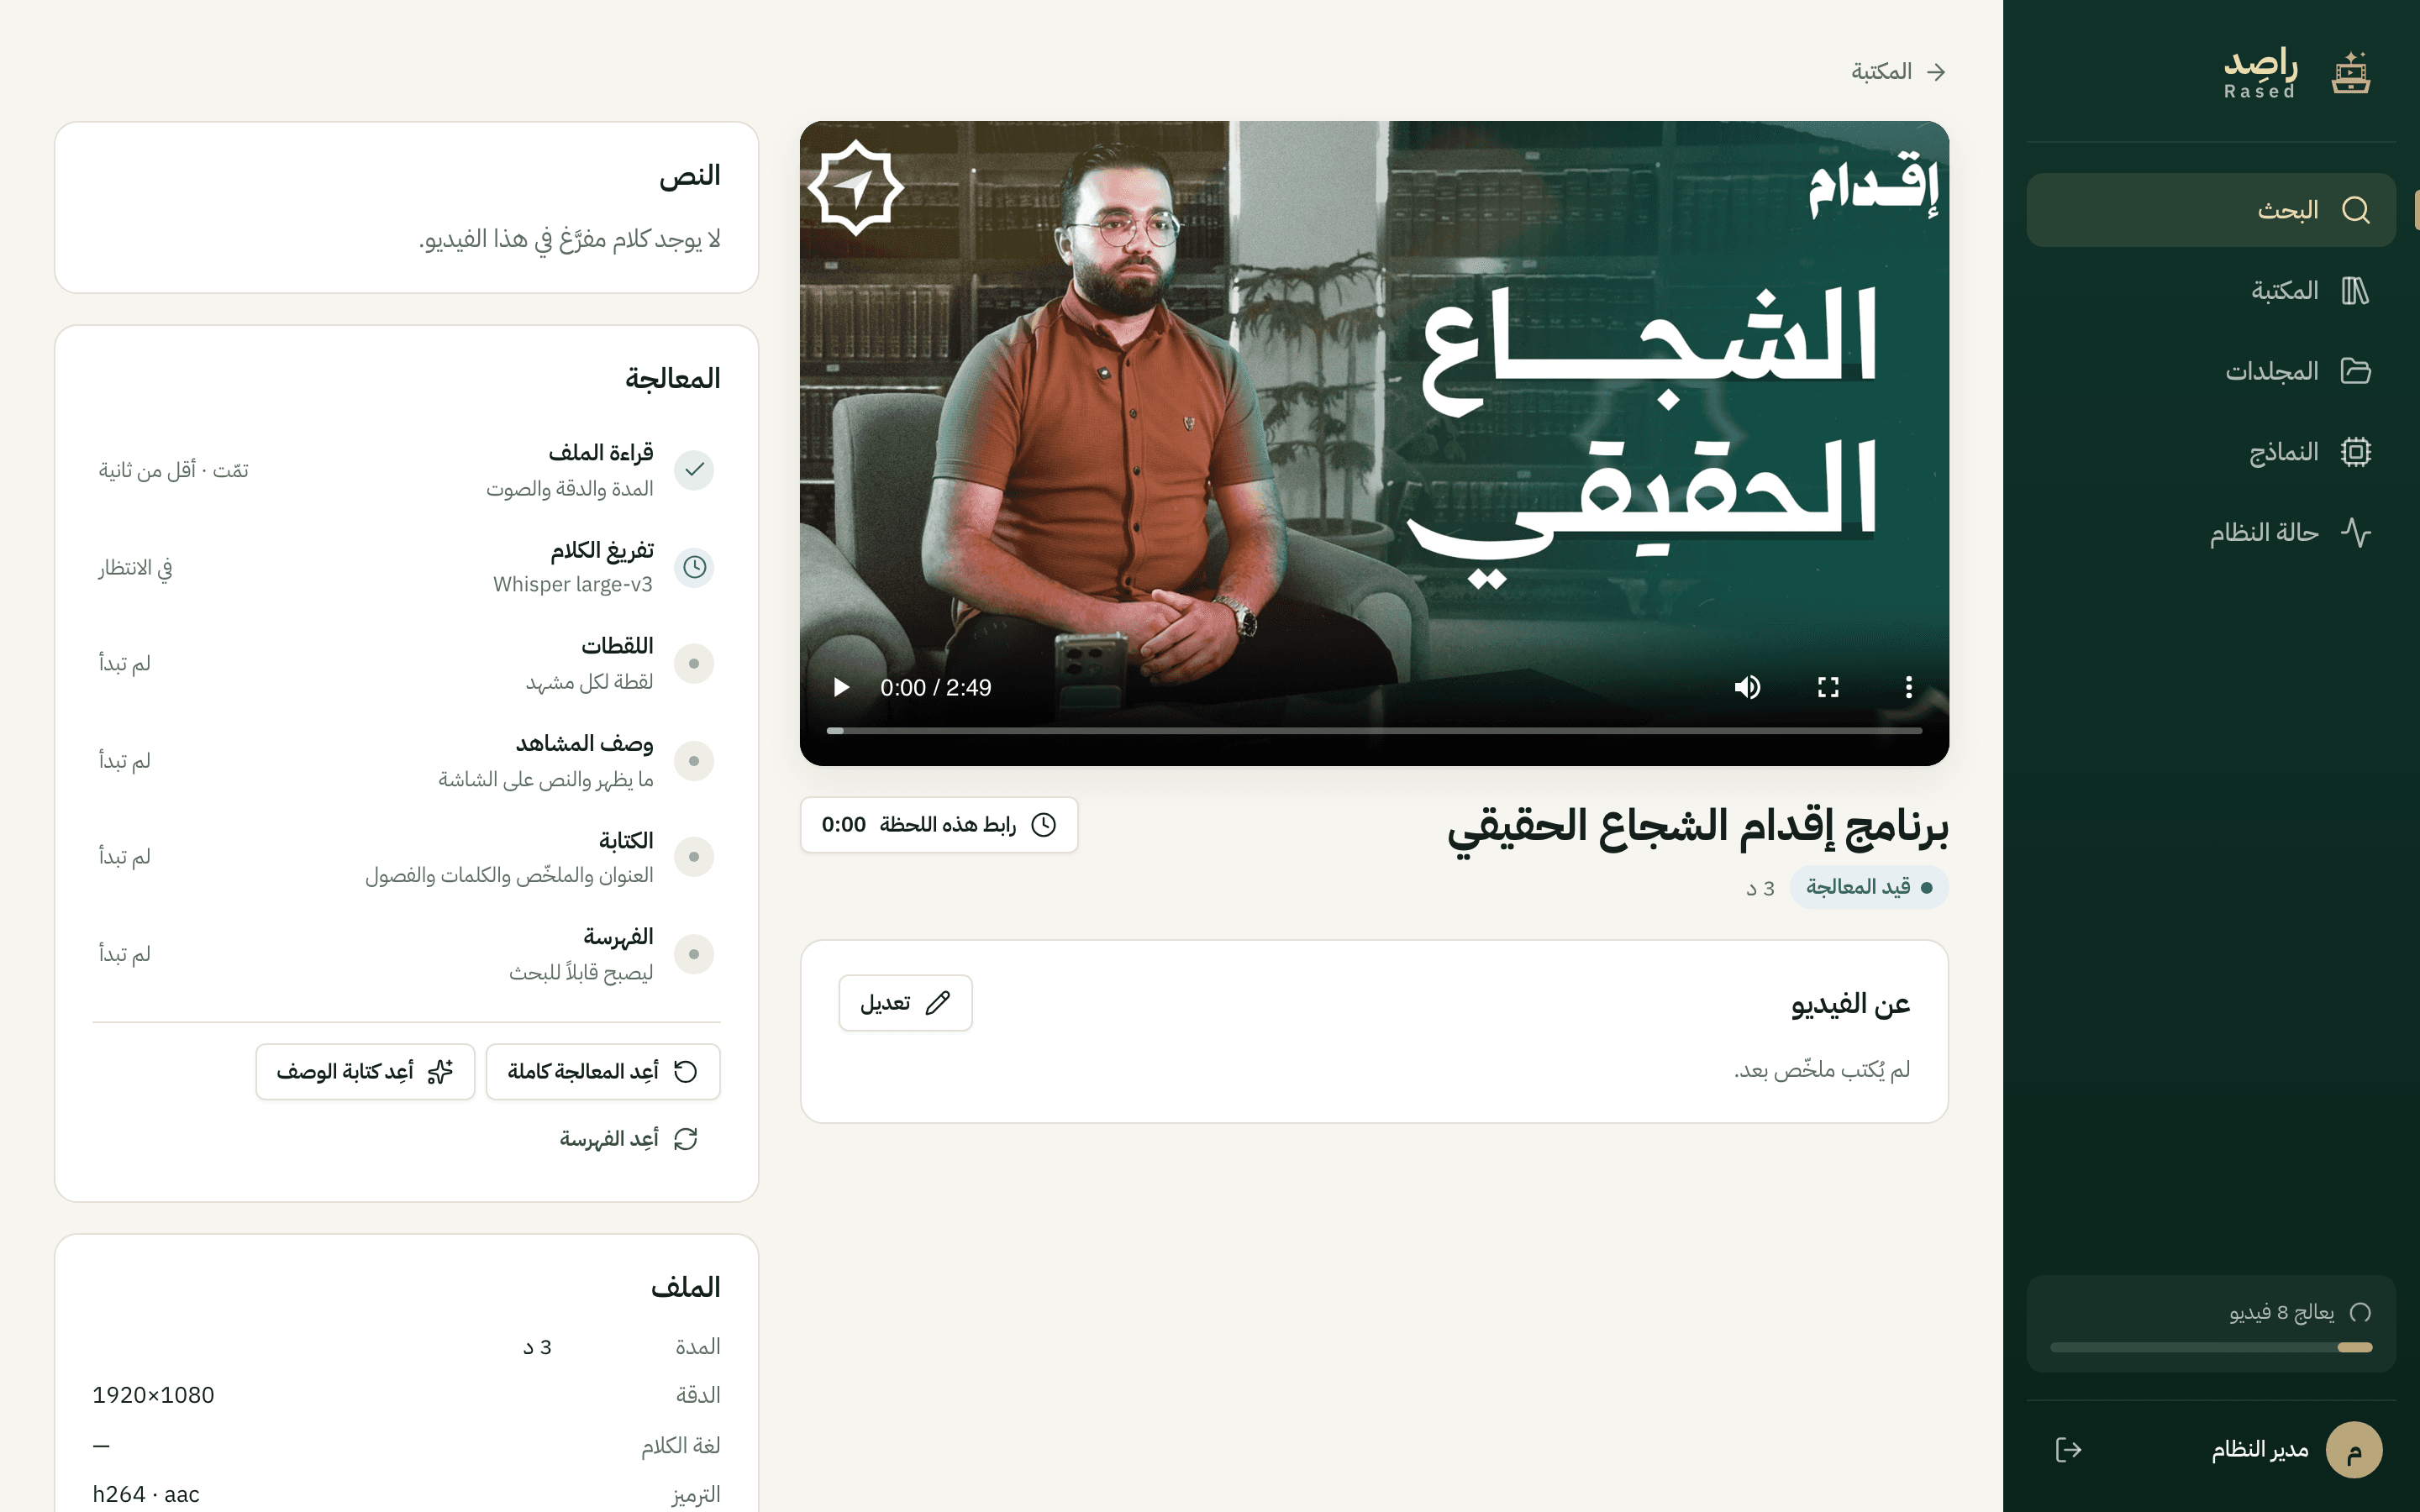
A staged processing pipeline: speech with Whisper large-v3, scene vision and on-screen text with Gemma 4 E4B, then structured writing constrained by a JSON grammar and map-reduce for long videos.
- 02
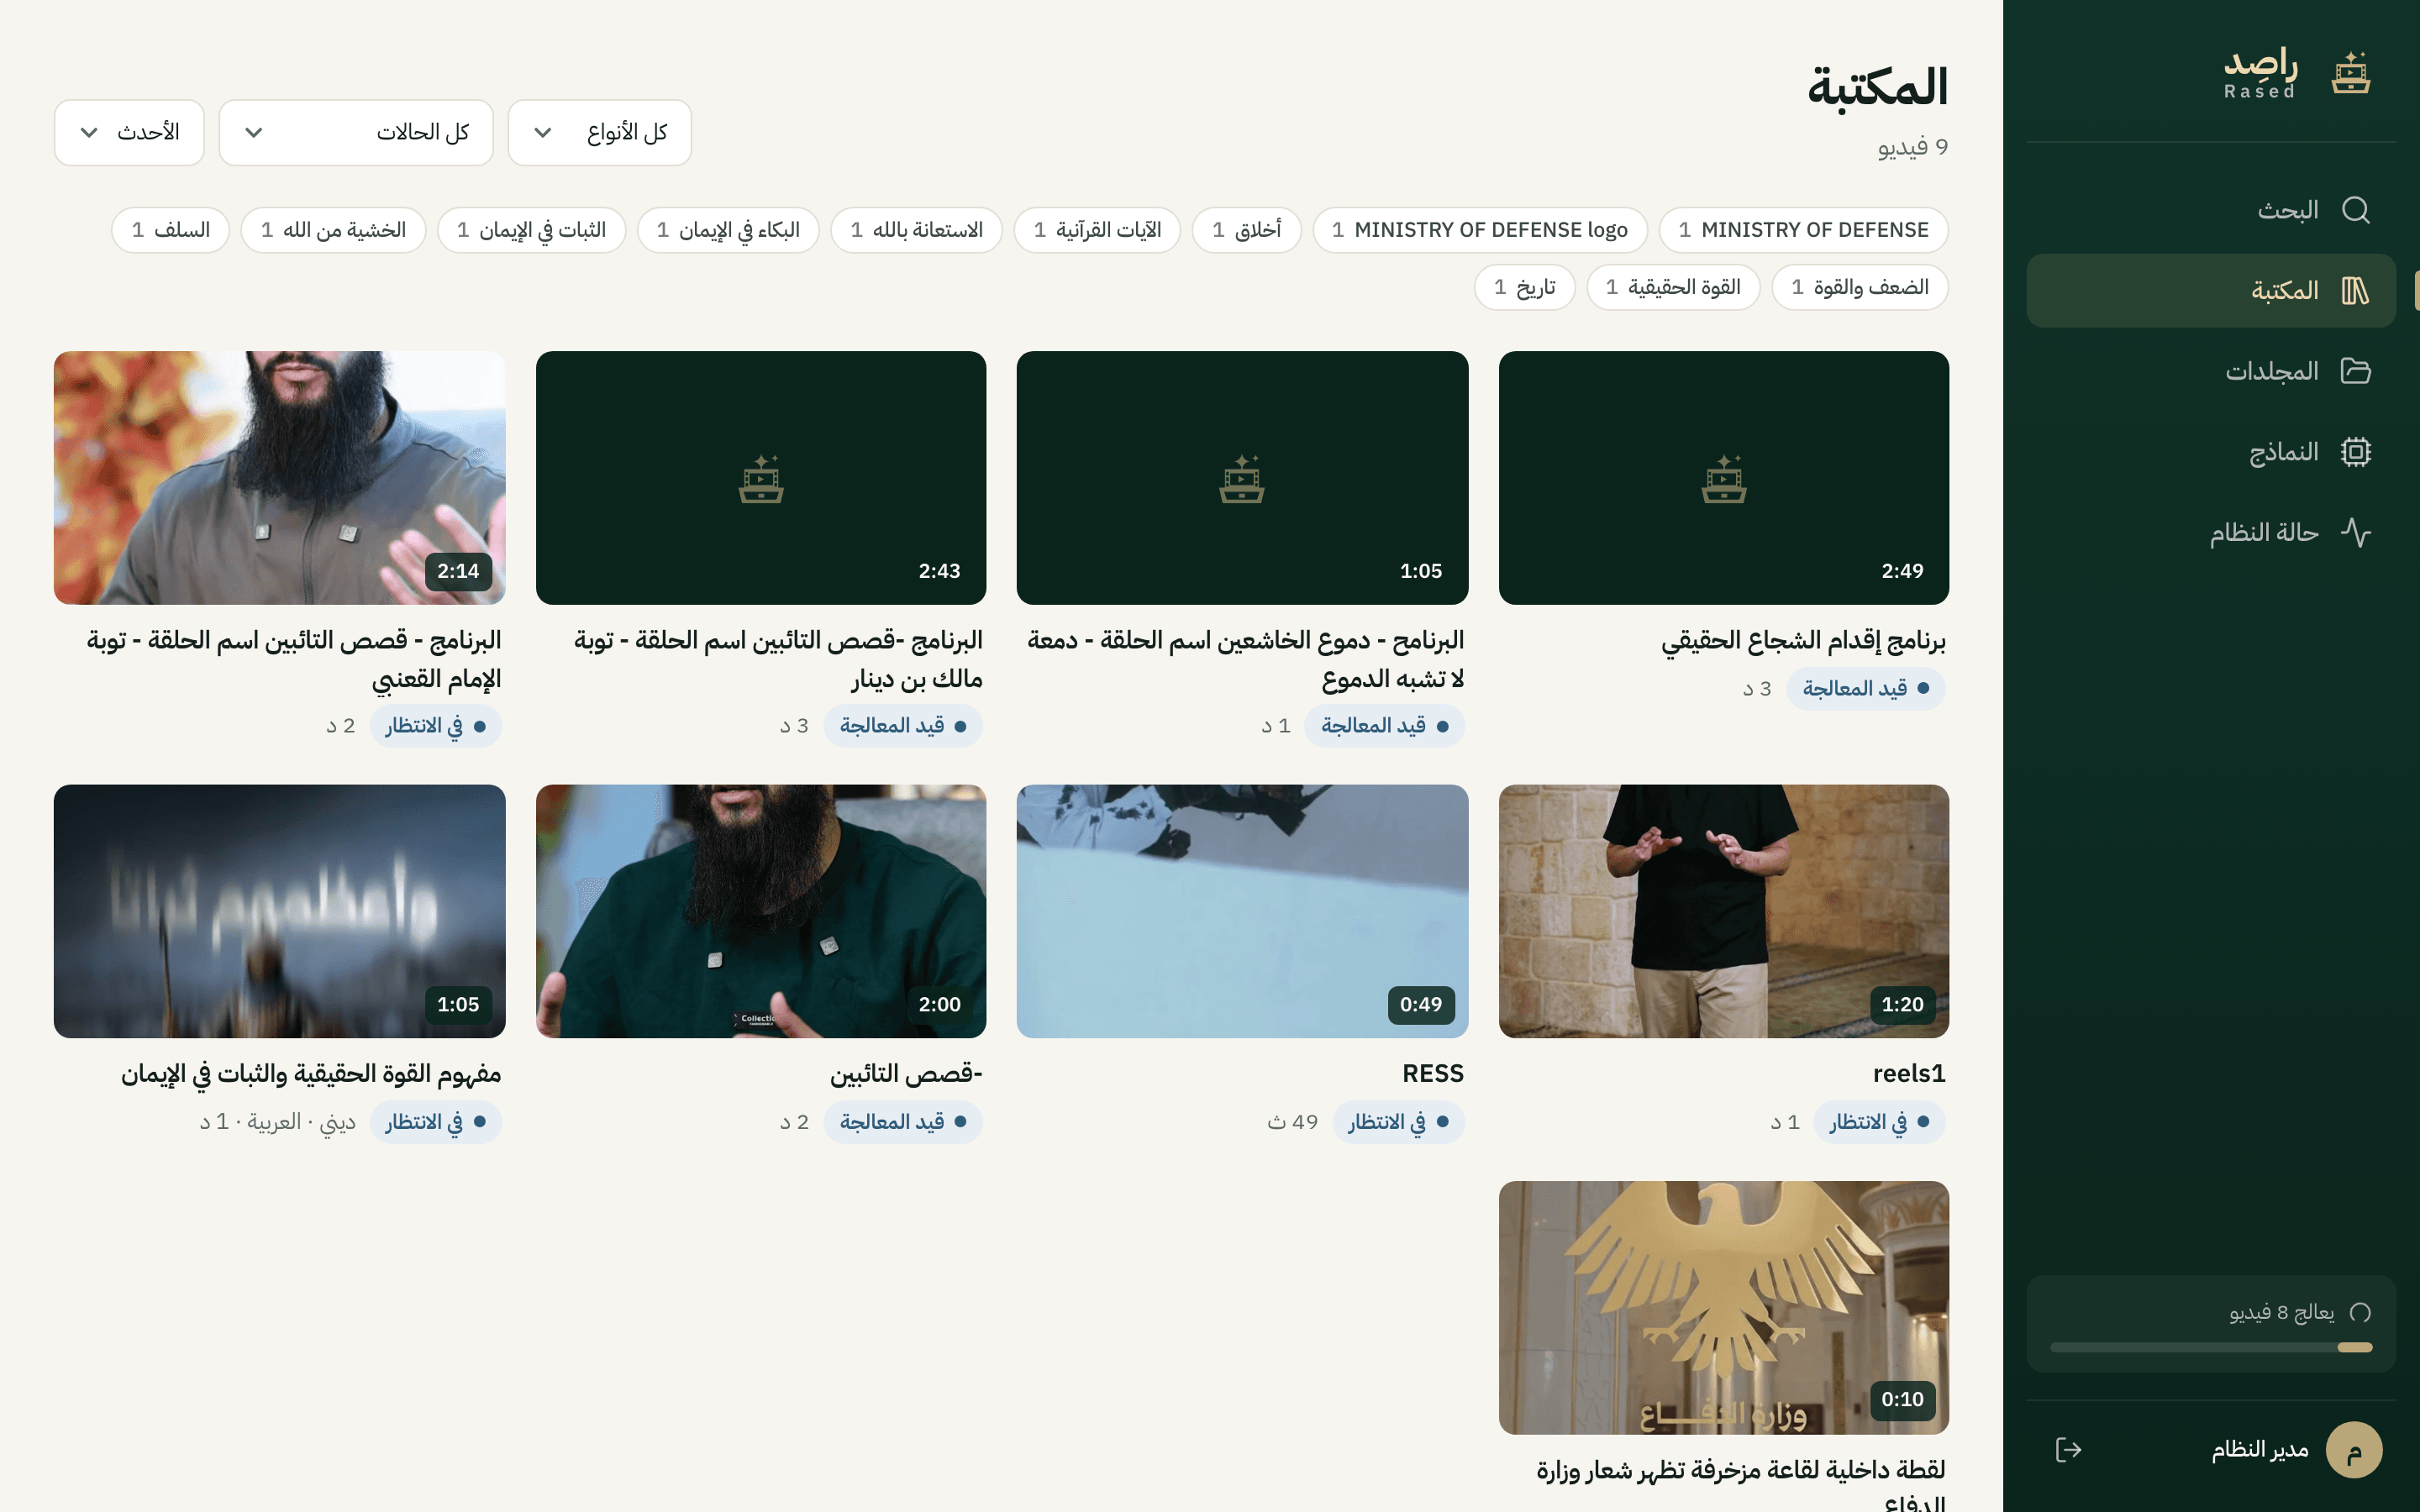
Hybrid retrieval in PostgreSQL — Arabic light-stemmed full text, trigram and bge-m3 vectors — fused by Reciprocal Rank Fusion and reranked by bge-reranker-v2-m3.
- 03
Results that open the player at the matched moment, with a transcript that follows playback and editable metadata that survives re-analysis.
- 04
Two distributions from one codebase: a Docker server for an organisation and a Windows / macOS desktop app that runs every model locally and keeps the machine awake while it works.
- 05
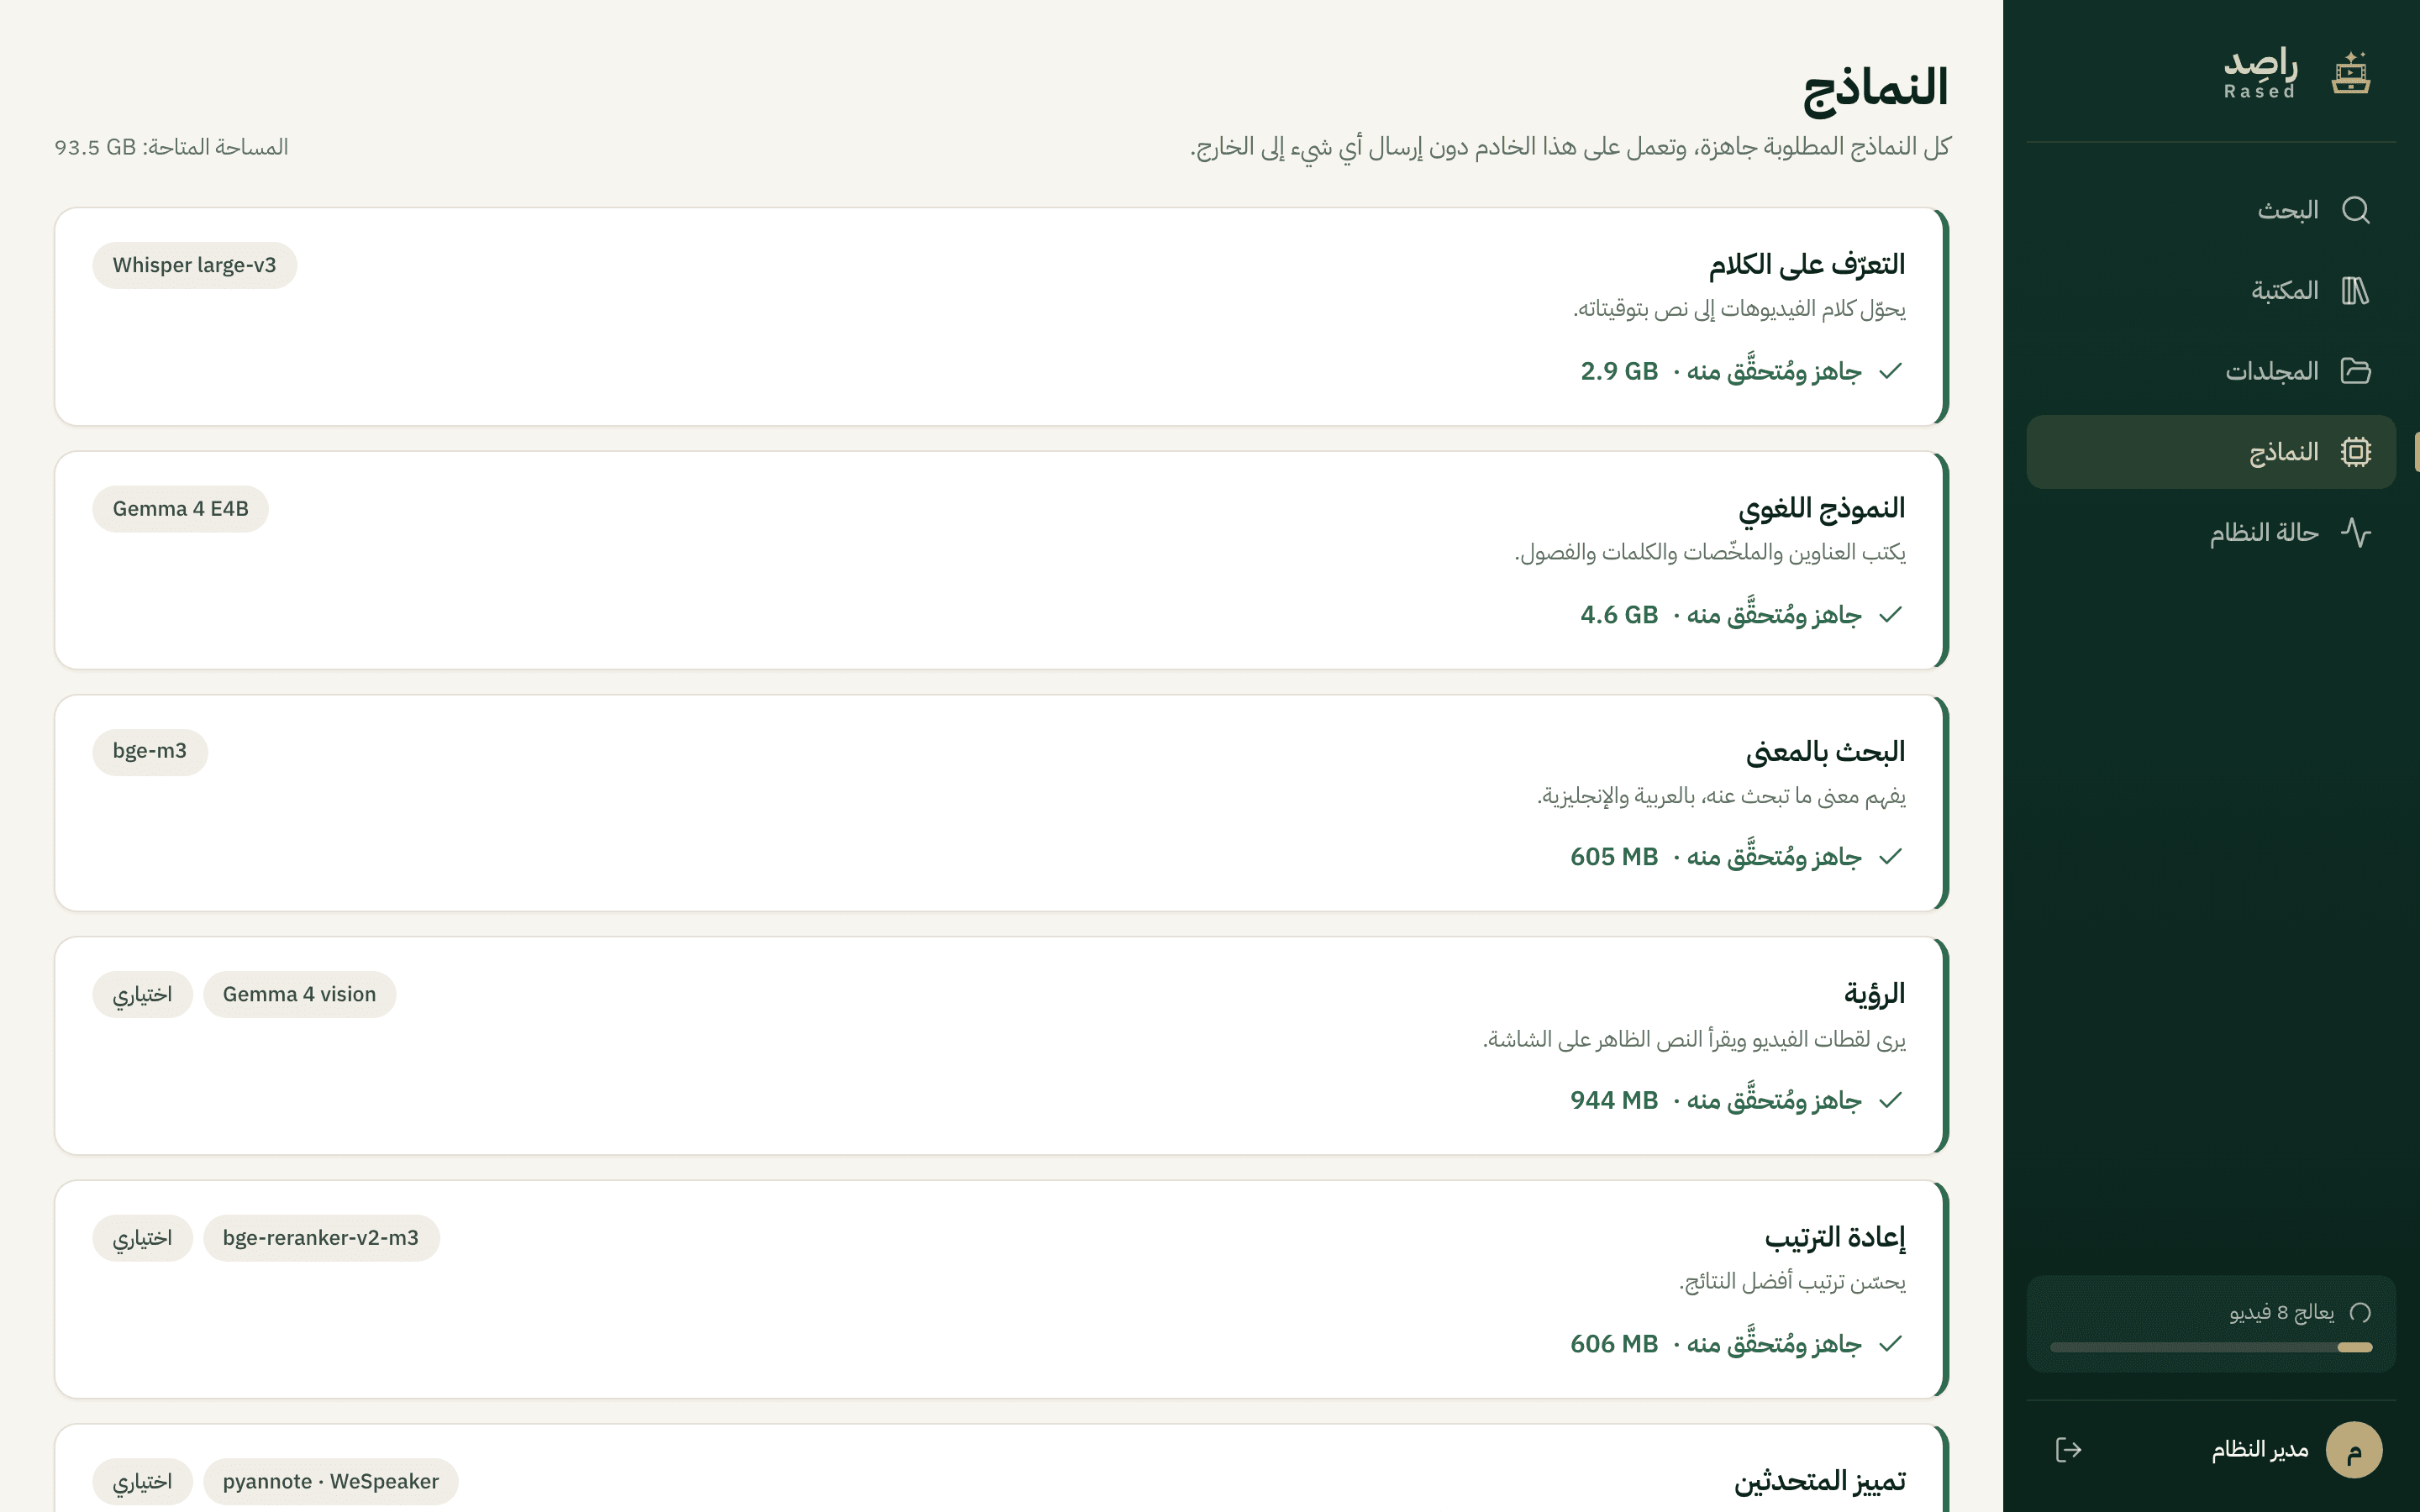
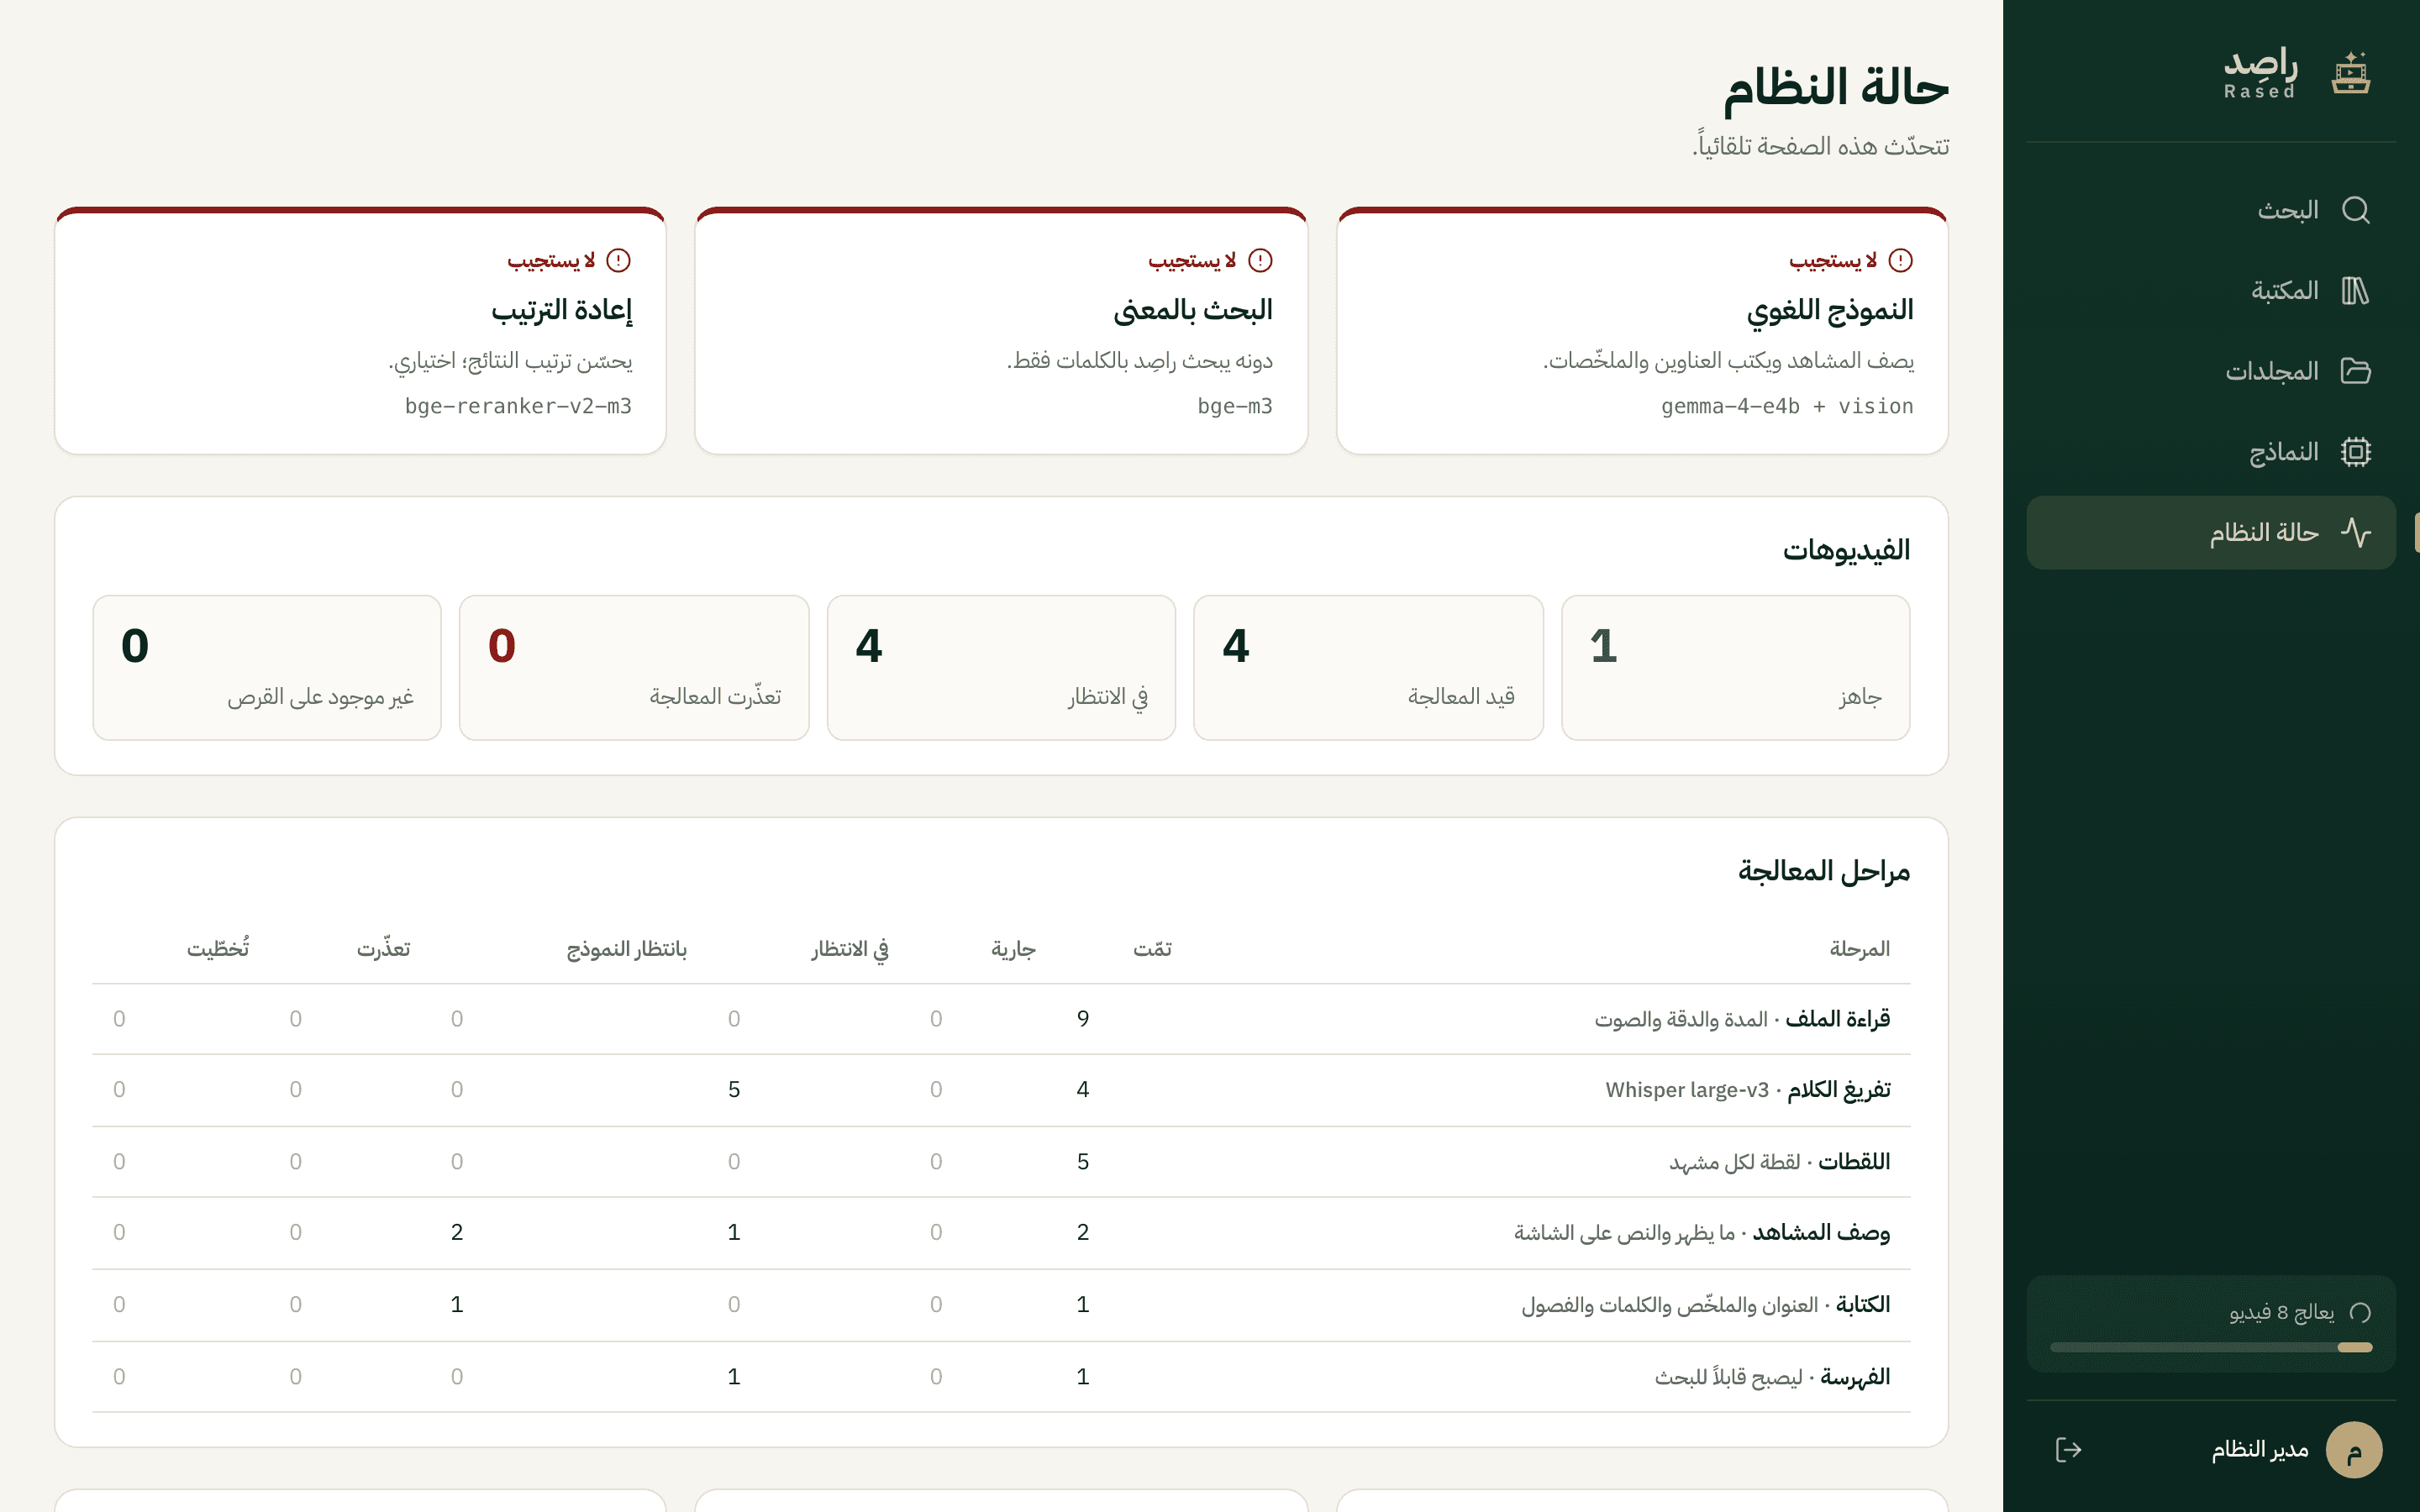
Operational screens for model downloads (pause, resume, or adopt a file already on disk), per-stage processing status and disk headroom.
03 — Architecture
How the pieces fit.
- L1Interface
- React + TypeScript + Vite
- Arabic-first RTL
- Every screen addressable — a moment is a shareable URL
- L2API
- Django + DRF, /api/v1
- OpenAPI docs
- Session auth with CSRF-trusted origins
- L3Pipeline
- Queue workers per stage
- faster-whisper
- llama.cpp servers: LLM, embeddings, reranker
- L4Retrieval
- PostgreSQL + pgvector
- FTS + trigram + bge-m3
- RRF fusion → cross-encoder rerank
Requests flow top to bottom · each layer depends only on the one beneath
04 — Decisions that matter
Decisions
One database, three retrievers
Lexical, fuzzy and semantic search all live in PostgreSQL and are fused with RRF — no separate vector store to secure, back up or keep consistent.
Grammar-constrained generation
The model writes metadata through a JSON grammar, so every title, chapter and keyword is parseable by construction rather than repaired after the fact.
Upgrade without migration pain
The product was renamed from Oqab to Rased while the code kept its package and setting names, so servers installed from v0.1.0 upgrade with zero configuration changes.
05 — Security & trust
- No cloud APIs and no telemetry — models, media and index stay on the machine.
- Model files verified by SHA-256 before they are loaded.
- Administrator-only folder management; every other role is read and search.
06 — Stack
- Python
- Django
- PostgreSQL
- pgvector
- llama.cpp
- Whisper large-v3
- Gemma 4 E4B
- bge-m3
- React
- TypeScript
- Docker
- Inno Setup
07 — In the product
Next case · 02
Shaheen
An institution’s AI that never touches the internet.